Ticket Meta — Hive Data Warehouse for Flight Search
HiveQL data-warehouse layer for a flight ticket meta-search and recommendation project: external staging tables, managed ORC tables and pre-aggregated analytics tables.
Built by Redoan Uzzaman, Full-Stack Developer & AI Engineer.
Overview
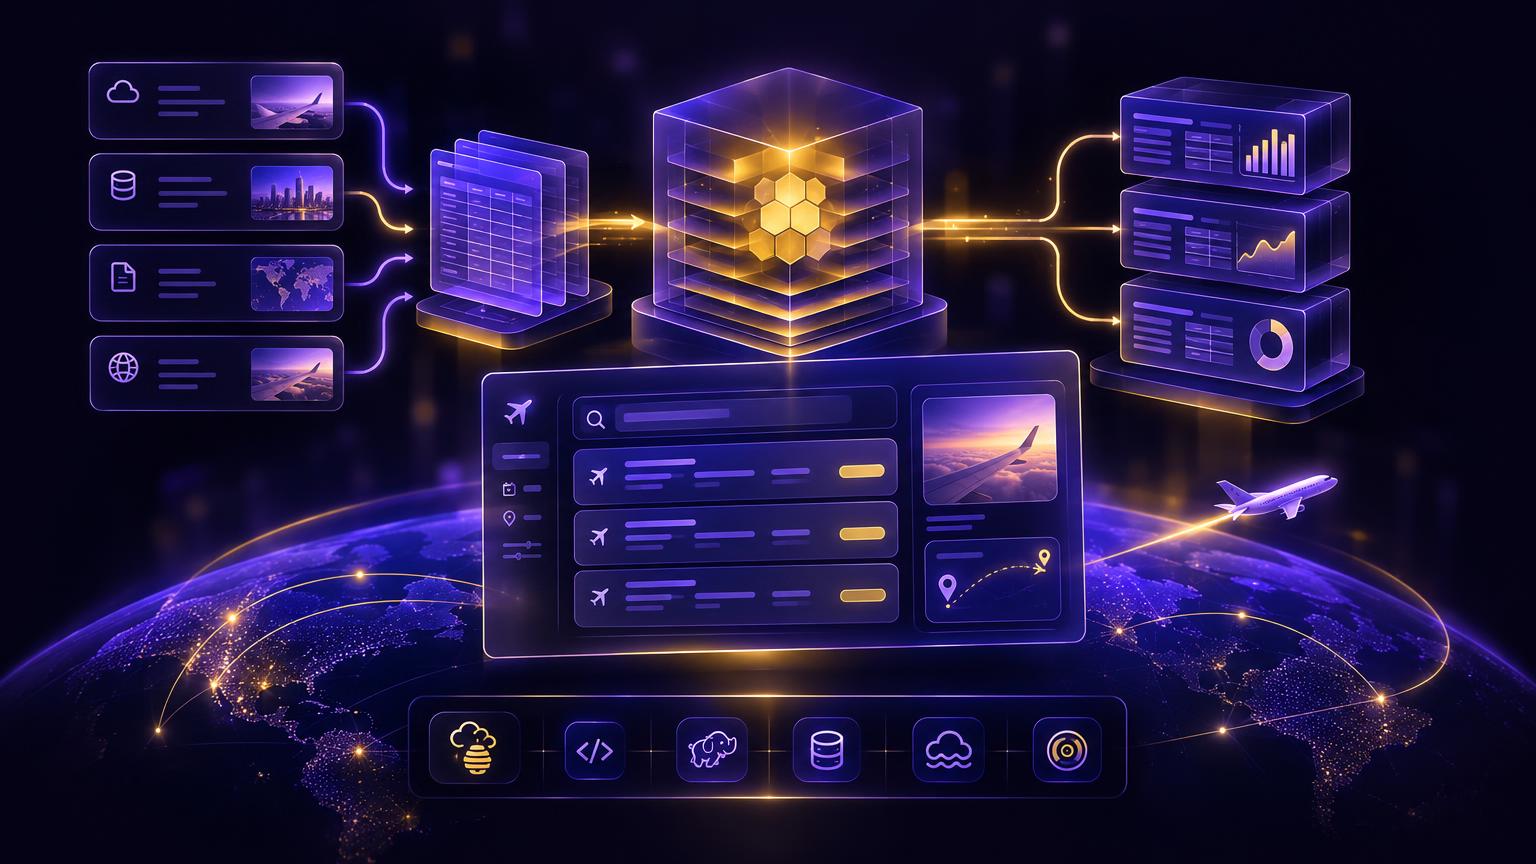
This repository contains the data-warehouse foundation of the Ticket Meta flight search and recommendation project, which later grew into the Data Turbulence analytics platform. It defines, in ordered HiveQL scripts, how raw aviation data is loaded, optimised and summarised on a Hadoop cluster.
How it works
The scripts run in sequence:
- Database: creates the project database.
- External tables: stage the raw CSV data for itineraries, airports, airport frequencies, countries, regions, runways and navigation aids.
- Managed tables: copy each dataset into Hive-managed tables. The itineraries fact table, about 30 GB of raw data, is stored as ORC with Snappy compression for much faster scans.
- Aggregated tables: pre-compute the queries the application needs most, including cheapest destinations, price by month, airline comparison, airline market share and distance versus price.
- Verification: a final script checks that every table loaded correctly.
Why it matters
Splitting the work into staging, managed and aggregated layers keeps raw data untouched and lets the web application answer common questions from small summary tables instead of scanning the full fact table each time. Numbered scripts make the warehouse easy to rebuild from scratch on any cluster.
Key Features
- Ordered, reproducible HiveQL build scripts
- External staging tables for 7 aviation datasets
- Managed ORC fact table with Snappy compression (~30 GB raw)
- Pre-aggregated tables for prices, destinations and airline market share
- Verification script for loaded tables
Tech Stack
- Apache Hive
- HiveQL
- Hadoop
- HDFS
- ORC
- Snappy
Want something like this built?
Redoan Uzzaman takes on AI, automation and full-stack projects for clients worldwide.